Field notes · getting more variety from a design model
The model can't roll its own dice
We wanted more variety from a coding model without giving it extra build attempts. Asking it to be creative was not enough. Part one shares seven lessons from the experiments. Part two follows with five findings about building a human-reviewed design catalog and a repeatable draw.
Impeccable v4 · about 30 skill iterations · about 200 sampled concepts · about $2,600 in evaluations · July 2026
In this article: two parts, twelve findings
Creative prompts kept producing the same concept.
We tried sixteen creative framings: a demanding client, design vocabulary, world-building metaphors, and a pep talk about bland design. Thirty of thirty-five responses proposed the same concept. The wording changed more readily than the idea.
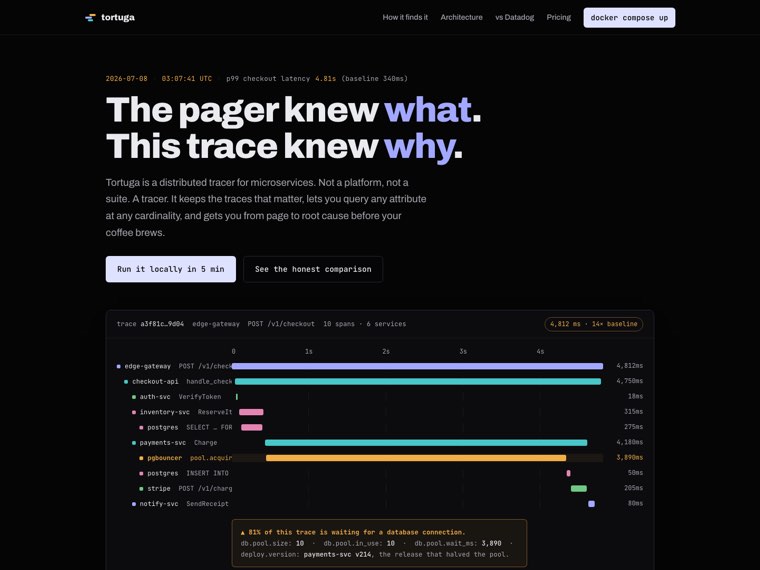
bland-epidemic → "The page is a trace. Every section is a span in one incident's waterfall…"
demanding-client → "The page is a trace. Every section is a span in one 2,340ms failing request…"
world-building → "The page is a trace. Every section is a span in one root waterfall…"
drenched-in-character → "The page is a trace. Every section is a span in one continuous waterfall…"
Here, each version imagined the page as a trace: a timeline showing the steps in a software request. Stronger appeals to creativity kept bringing us back to that same design.
Rejection revealed the next default.
“Write down your first three ideas, discard them unseen, build the fourth.” Prompts like this moved the model away from its first choice, but repeatedly landed on its second.
The pattern held across the rejection methods we tried, including asking the model to borrow from a related field it chose itself. We were getting two dependable defaults. Rejecting one did little to widen the range.
A varied shortlist still had a predictable winner.
Asking the model to derive seven directions from the audience’s world, with a reason for each, produced varied lists. Then “build the most resonant one” kept selecting the same winner. The variety disappeared at the choice.
1. the trace waterfall ← the usual choice
2. the postmortem doc ← the choice after rejection
3. the terminal session ← assigned by the script and built
4. the man page 5. the pager timeline
Our solution gave the model and the script different jobs: the model proposed relevant directions; the script randomly assigned which one to build.
- ProposeThe model develops a shortlist grounded in the audience.
- AssignA script draws one option from that shortlist.
- BuildThe model implements the assigned direction.
A later comparison tested whether assignment was necessary. When the shortlist remained open to selection by the model, a simulated user, or a rejection rule, option one won in 27 of 30 packets. The script had to assign the direction, rather than hand back a menu to rank again.
Each draw also produced a reproduction key. A disappointing selection could be replayed and investigated.
The product’s culture shapes the available ideas.
For a product rooted in Polish television, the model found seven promising directions. They included end-of-film voice credits, newspaper TV listings, teletext, video-rental shops, and dubbing scripts. For site reliability tools, a list of seven still circled around terminals and incident reports.
That made a curated pool of references from other fields useful: a naturalist’s field guide, for example, or a newspaper sports section. We compared these with the model’s own ideas on two questions:
- Will the audience connect with it?
- Will it make the product clearer?
References from outside the category helped when the model’s list was repetitive. When the product already offered rich cultural material, its own references could win.
Our safeguards were making the work timid.
We had added a “costume check”: if a visitor would notice the borrowed form before the product, the candidate fails. Then we realized it would reject our own 10/10 human reference, a site built as teletext. Its form was immediately recognizable, and the task was still easy.
Our prompt contained five discouraging instructions for every encouragement to commit. The results looked tentative. We removed the check and changed the order: commit to the concept first, then refine its clarity and usefulness. That produced the campaign’s biggest single improvement in design quality.
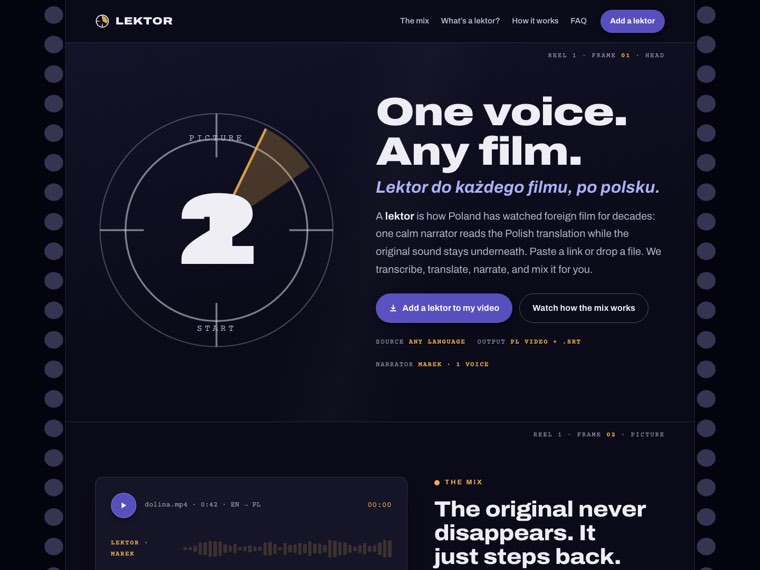
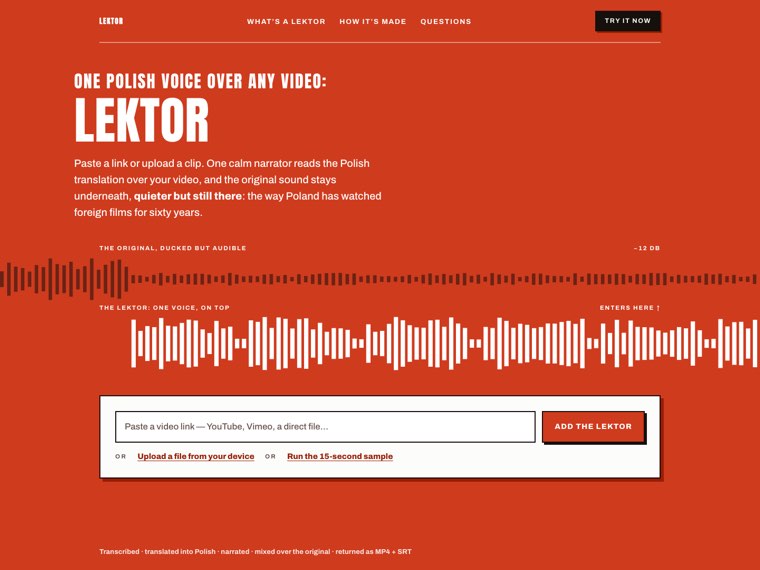
A new visual style can hide the same old layout.
A distinctive concept did not automatically change the palette, layout, and motion. One page had teletext in every detail: page-number labels, pixelated level bars, and four colored navigation buttons. Underneath it was a conventional marketing grid. The styling made that easy to miss.
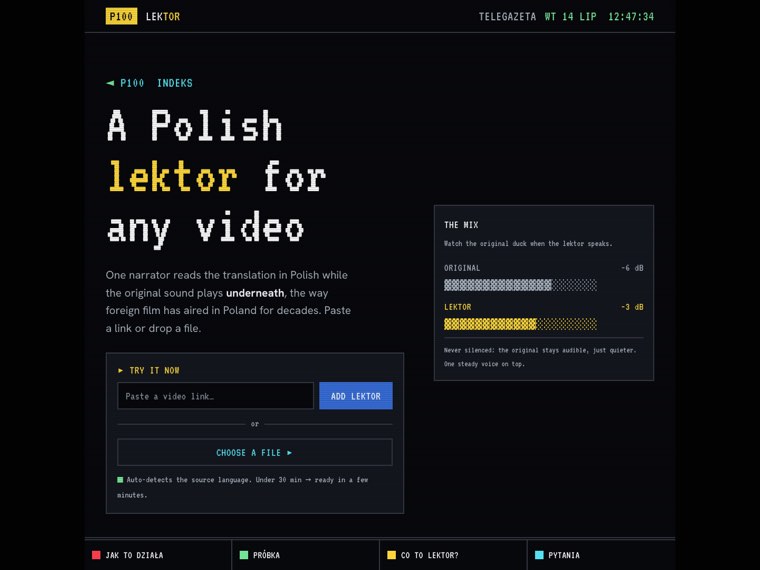
We tried asking the builder to imagine the page without color or texture and check its structure. A silent check still produced the standard layout. Requiring a written verdict added work and reduced quality, so we removed the check from the build process.
The instruction that survived was “borrow the form’s skeleton, not its clothes.” The reference should shape how the page is arranged. We kept structure checks for the finish, using a wireframe grader and a fresh reviewer instead of interrupting the builder to grade itself.
Compare the build with what it promised.
The model could promise a page structured as a software trace, then build a standard opening section. Nothing was comparing the result with that promise. Generic quality reviews made some pages busier without improving them.
We made the design intent explicit. At this stage of the experiment, the model wrote a five-part direction contract in a comment at the top of the generated file.
THESIS: the one idea this page owns, and the category default it refuses
OWN-WORLD: palette + components recognizable with all content removed
STORY: what the visitor understands, believes, does
FIRST VIEWPORT: the exact composition, and where the primary action sits
FORM: chosen form, its position on the list, and the seed key that picked it
Reviewing the contract inside the original build conversation still let gaps through. A separate reviewer agent compared the rendered page with each promise and rebuilt the missing parts while the builder continued its work. The contract gave that review a concrete target.
This was the experiment’s format. Today, the direction contract lives in a surface brief; see the New work guide for the current workflow.
What changed in the results
We kept the model, briefs, and single-run constraint the same as the baseline. The workflow changed. The project’s design director recorded these judgments as the campaign progressed:
| Checkpoint | Human verdict (design director) |
|---|---|
| baseline | "all boring and bland, competent but not good" · 0/9 wins vs competitor skill on the hardest task |
| + dice | "massive improvement, especially on the redesign" |
| + form scale | "first time close to the competitor benchmark" |
| + commit-first | "truly commits to the concept, most distinct so far, by a margin" |
| full architecture | first 8/10 of the campaign · "I can't believe we got something so unique and good" · category beat the competitor skill AND the bare model |
A separate model compared pairs of screenshots. Earlier iterations had scored 30–40% against the strongest comparison skill. The final workflow won 100% of decisive pairs on the tasks we had examined in depth. It also showed positive results in four new categories it had not been tuned on.
How these results were evaluated
Concept tests sampled design intent as roughly 200-word contracts before paying for full builds. Human ratings came from the project’s design director. The automated comparison judged screenshots in both presentation orders to reduce position bias.
The selection experiment in finding three compared both mechanisms with matching draw keys and identical guidance. These findings describe the July 2026 campaign. The 100% figure covers decisive comparisons on the tested tasks; it is not a win rate across all tasks or coding models.
Part two Building the catalog
Give the dice something worth choosing.
The experiments gave us a way to escape repeated choices. The next job was to build a better set of choices: visual systems that could become useful interfaces. That meant authoring references, rendering them, and putting each one through human review.
A useful reference brings a graphic system.
“Record covers” is a broad theme. A 1950s Blue Note session sleeve offers specific decisions about type, color, and composition. We looked for references with enough structure to guide a whole interface.
Each entry describes its visual rules and a scene that shows them in use. A world supplies an identity; a composition supplies page structure. Some references can do both. Composition decks are organized around what the visitor needs to do: choose, operate, read, or explore.
The strongest references did something with their visual language. Du Bois’s data portraits made an argument; Massin’s stage pages performed dialogue; television captions gave speech a visual rhythm. A respected source alone was not enough. Its system had to contribute to the interface.
The approved pool included Fillmore Handbill, Wax Print Market, Teletext Service, Du Bois Data Portraits, and eBoy Pixorama.
Review the rendered result.
Agents authored the entries; a human decided what belonged in the catalog. New entries arrived as pending. A generated design-system board established the visual rules, and a page example built from that board showed how they worked together.
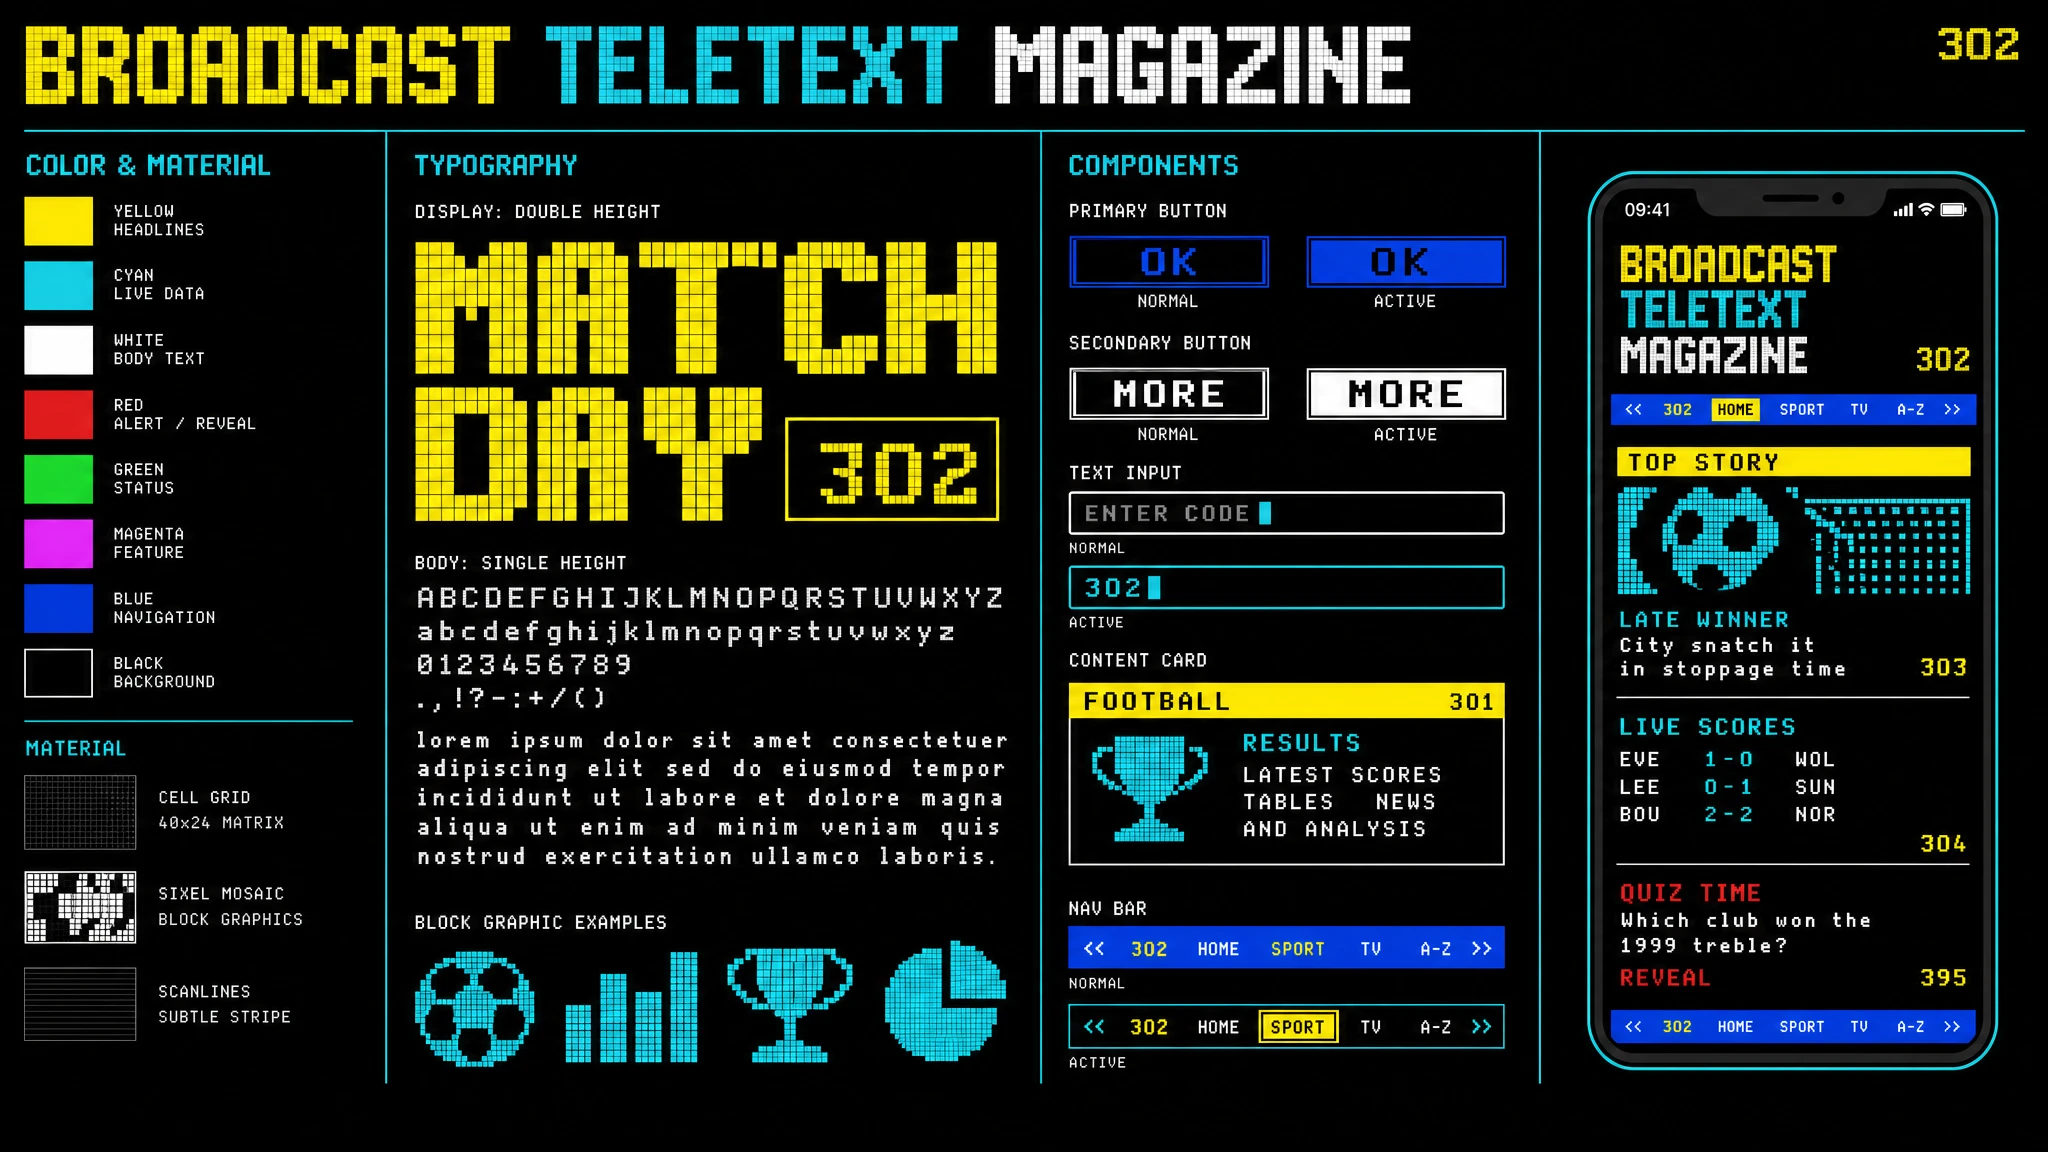
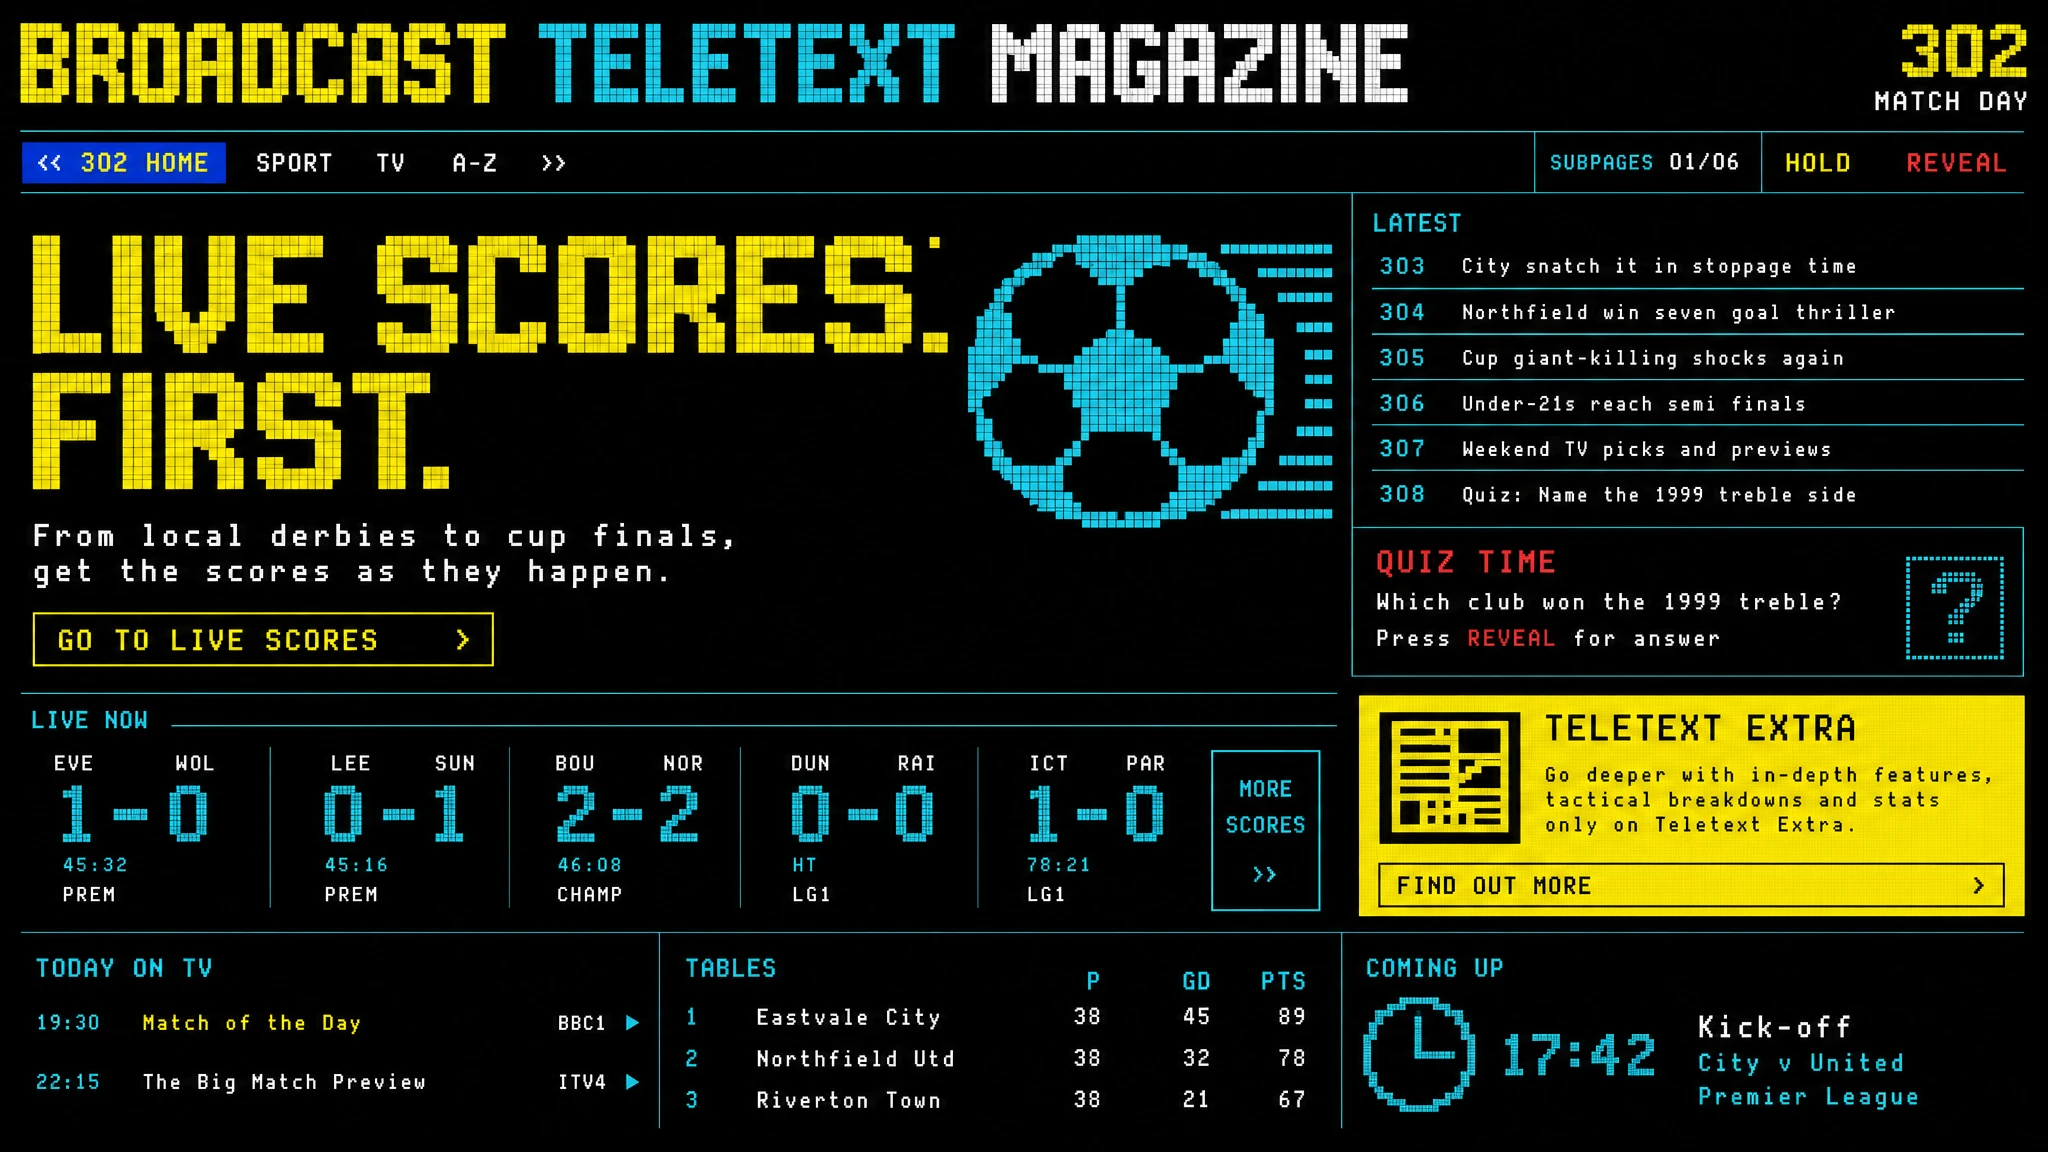
The reviewer approved or rejected the entry, rated approvals, and left notes to guide later work. On July 21, 2026, the catalog held 375 entries: 188 approved, 172 rejected, and 15 still pending. Of the approvals, 83 received the highest, three-star rating.
A recurring rejection was “doesn’t translate to interface.” Revising a reference helped when the problem was taste; it rarely rescued a source with no usable graphic system. Rework succeeded in about a third of cases reported in the campaign.
We also rejected familiar AI defaults, even when they had a legitimate design history. The Frutiger Aero entry was rejected because its treatment resembled the glassmorphism then common in AI output. The catalog has to respond as those defaults change.
More of a successful style soon becomes repetition.
We tried going deeper into the sources that had produced our best entries. A round of twelve yielded three approvals and no top-rated entries. The recurring review note was “too similar to others we already have.” A new name did not make another green-on-black screen a new visual system.
We shifted toward small rounds exploring new territory, with an expected approval rate of 25–40% at that stage. Asking an authoring agent to name a similar catalog entry had encouraged near-duplicates. We instead checked what each candidate would add to the collection.
Where a visual family was already represented, another entry had to improve on it. That raised the bar for familiar ideas while leaving room for distinct ones. In one round, four of seven entries were approved, all with the highest rating.
A draw should offer variety you can revisit.
The draw combines visual references with page structures suited to the task. It normally offers six world candidates across three kinds of source, plus up to three compositions. The references include rendered boards and page examples to show the level of finish the design should reach.
In the campaign, two builds whose models saw reference cards were the strongest in their group; a build without cards was the weakest. We saw the pattern again. It was a useful signal to keep investigating, rather than enough evidence to isolate the cards’ effect.
How the draw works now
- Ratings influence the draw. Two- and three-star entries have equal weight; one-star entries have half that weight. References marked as niche are normally held out of general draws.
- Another hand explores further. Re-rolls exclude previously dealt worlds while that source group has alternatives. An exhausted group can reuse entries.
- The selection is repeatable. The same inputs, catalog and review data, and selection logic reproduce the draw. Save the key and settings to investigate a result.
The original version gave three-star entries extra weight. That changed after highly rated references appeared too often. Reproducibility applies to the selection of references.
The catalog became a public API.
GET /api/roll returns a selection from the approved pool. Clients receive the chosen entries and their reference-card links, so they can use the catalog without downloading it in full.
The API records which entries it deals. A separate choice report records what was selected, giving us another signal for future catalog reviews.
About draw and choice records
The application’s event writer records catalog IDs and selection metadata, such as mode and whether a hand was steered safer or bolder. The choice-reporting client does not include project-derived candidate names.
In the concept-seed client, DO_NOT_TRACK or IMPECCABLE_NO_TELEMETRY disables the choice report. Fetching a draw is a separate request.
Explore a hand on the homepage, or see how a chosen direction became a working interface in the Neo Mirai case study.
Better outcomes came from better choices, room to commit, and a review that checked whether the idea survived the build.
Research conducted with Impeccable v4 in July 2026. Historical counts above come from the July 21 catalog snapshot; draw mechanics are described as currently implemented. Evaluation methods and results.